Best Mini PC for Local AI (2026): Run Chatbots and LLMs Privately at Home
Running a language model on your own mini PC keeps your prompts and files at home, works offline and has no subscription. Whether it works well comes down to two numbers: how much memory the graphics chip can use, which decides which models fit, and how fast that memory is, which decides how quickly they answer. Here are the mini PCs that get both right, with measured speeds rather than marketing claims.
In short
For large models, buy an AMD Strix Halo mini PC with 128GB: the Minisforum MS-S1 Max is the best equipped (128GB standard, dual 10GbE, a PCIe slot), and the GMKtec EVO-X2 is the more compact choice. They run mixture-of-experts models such as GPT-OSS 120B at comfortable speeds. For everyday assistants with 7B–14B models, a Ryzen AI 9 HX 370 mini PC like the Peladn HO5 costs far less. The Minisforum AI X1 Pro-370 is the pick if you want memory you can upgrade later.
- 1Minisforum MS-S1 MaxBest for large models · Strix Halo · 128GB · dual 10GbEDetails
- 2GMKtec EVO-X2Most compact Strix Halo · 64GB or 128GBDetails
- 3Peladn HO5Best value for small models · Ryzen AI 9 HX 370 · 32GBDetails
- 4Minisforum AI X1 Pro-370Upgradeable memory · up to 128GB DDR5 · OCuLinkDetails
- 5Minisforum N5 MaxAI and NAS in one box · Strix Halo · 5 drive baysDetails
What changed in this update (Oct 12, 2026)
We rebuilt this guide around published measurements. The previous version gave speeds no independent test supports — for example 18–25 tokens per second for a 70B model on Strix Halo, where measured results are about 5 — and prices that no longer apply: 128GB Strix Halo mini PCs now cost well over $3,000 after the 2026 memory price rise. We added the Minisforum MS-S1 Max, the Minisforum AI X1 Pro-370 and the N5 Max, moved the Beelink SER9 Pro and ACEMAGIC Retro X5 to “Also worth a look”, and corrected the SER9 Pro’s Wi-Fi (Wi-Fi 6, not Wi-Fi 7).
How much memory do you need?
The model must fit in the memory the graphics chip can use: about 5GB for an 8B model, 20GB for a 32B model, 40GB for a 70B model and over 60GB for GPT-OSS 120B, plus room for the conversation.
These mini PCs have no separate graphics card: the processor and its integrated GPU share the system memory. Part of it is reserved for the GPU, so a 32GB machine typically gives the GPU around half to three-quarters of its memory, and a 128GB Strix Halo machine up to 96GB in Windows (Linux users report allocating more). Memory is soldered on most of these machines, so choose the capacity at purchase.
| Model size | Examples | Model file | Mini PC memory |
|---|---|---|---|
| 3–8B | Llama 3.2 3B, Llama 3.1 8B, Qwen3 8B | 2–5GB | 16GB or more |
| 14B | Qwen3 14B, Phi-4 | about 9GB | 32GB |
| 30B mixture-of-experts | Qwen3-30B-A3B | about 16–18GB | 32GB (64GB is more comfortable) |
| 32B dense | Qwen3 32B | about 20GB | 64GB |
| 70B dense | Llama 3.3 70B | about 40–43GB | 64GB minimum, 128GB recommended |
| 120B mixture-of-experts | GPT-OSS 120B | about 63GB | 128GB |
How fast will it answer?
Speed follows memory bandwidth. Strix Halo reads memory about twice as fast as a Ryzen AI 9 HX 370, and mixture-of-experts models, which use only a few billion parameters per word, run many times faster than dense models of the same size.
To write each word, the computer reads the active part of the model from memory. Strix Halo has a 256-bit memory bus (about 256 GB/s in theory); the Ryzen AI 9 HX 370 has a 128-bit bus (about 120 GB/s); and DDR5 SO-DIMM modules in dual channel give roughly 90 GB/s. That is why a dense 70B model crawls even on Strix Halo, while GPT-OSS 120B, which activates about 5 billion parameters per token, stays comfortable.
| Model | Ryzen AI 9 HX 370 | Ryzen AI Max+ 395 (Strix Halo, 128GB) |
|---|---|---|
| Llama 3.1 8B (dense) | about 13 | about 42–53 (7–8B models) |
| Qwen 14B (dense) | about 7 | — |
| Qwen3-30B-A3B (MoE) | about 10–16 for similar 35B MoE models | about 72–95 |
| GPT-OSS 120B (MoE) | does not fit in 32GB | about 31 (LM Studio) to 54 (tuned llama.cpp) |
| Llama 70B (dense) | does not fit in 32GB | about 5–6 |
For reference, people read at roughly 5 to 10 tokens per second, so anything above 10 feels fluid in a chat; long code or document generation benefits from 30 and more. The HX 370 figures come from LocalScore and a Ryzen AI 9 HX 370 laptop test; the Strix Halo figures from Level1Techs and llm-tracker.info, ServeTheHome and a consolidated set of measurements from September 2026. AMD’s own claim that Strix Halo generates up to 2.2× more tokens per second than an RTX 4090 on Llama 70B applies only because that model does not fit in the 4090’s 24GB.
1. Minisforum MS-S1 Max — best for large models
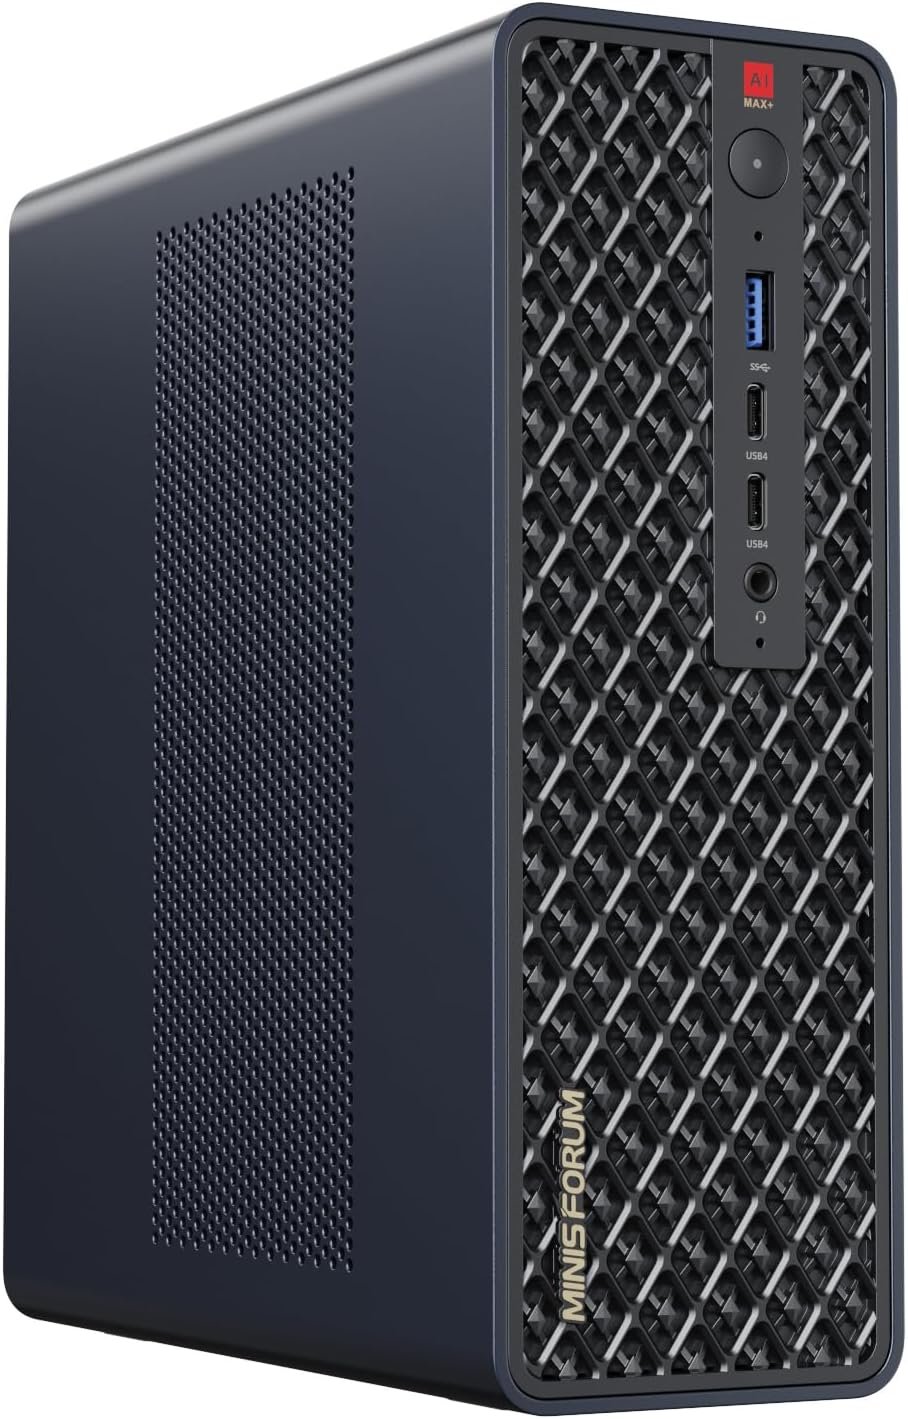
Minisforum MS-S1 Max
128GB of fast unified memory, a 16-core Ryzen AI Max+ 395 at up to 160W, dual 10GbE, USB4 v2 and a PCIe slot — a small AI workstation.
Check current price on AmazonThe MS-S1 Max is the most complete Strix Halo machine for AI work. It ships with 128GB, the configuration you want for 70B–120B models, and runs the processor at up to 160W in Performance mode. Notebookcheck rated it 84% and measured about 37,300 points in Cinebench R23 multi-core; ServeTheHome called it one of its favorite systems for local AI. Two 10GbE ports make it practical as a shared AI server on a home or office network, and the internal PCIe slot (wired x4) can take a network or storage card. The trade-off is noise: Notebookcheck found it too loud at idle in Performance mode until a BIOS update, and the quieter modes cost some speed. A 64GB version also exists; for AI, take 128GB. Read our Minisforum MS-S1 Max review.
- 128GB standard, up to 96GB for the GPU in Windows
- Dual 10GbE, two USB4 v2 80Gbps ports
- Internal power supply, PCIe x16 slot (x4)
- Audible fans in Performance mode
- Soldered memory
- One HDMI port, no native DisplayPort
2. GMKtec EVO-X2 — the most compact Strix Halo
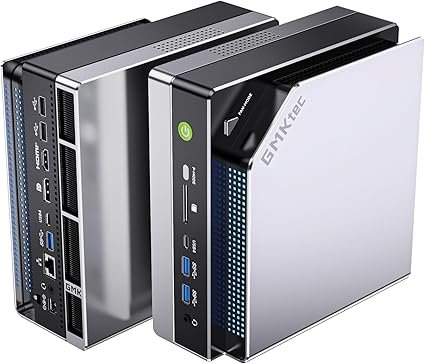
GMKtec EVO-X2
The same Ryzen AI Max+ 395 and Radeon 8060S in a true mini PC, sold with 64GB or 128GB of LPDDR5X-8000.
Check current price on AmazonThe EVO-X2 brings Strix Halo to a smaller, quieter box. Notebookcheck counted it among the best mini PCs of 2025 and found it comparatively quiet and cool. Memory is the decision: the 128GB version lets the GPU use up to 96GB, enough for GPT-OSS 120B or a 70B model with a long context; the 64GB version allows 48GB, which covers 30B-class models and 70B only at tighter settings. The listing we link is the 64GB configuration, so check the memory line if you want 128GB. GMKtec also released a cheaper 128GB variant with a 1TB SSD in July 2026. Read our GMKtec EVO-X2 review.
- Strix Halo in a compact mini PC
- Quiet and cool for its class (Notebookcheck)
- Also a capable 1440p gaming machine
- The 64GB version limits the GPU to 48GB
- Soldered memory
- Limited fan control
3. Peladn HO5 — best value for small models
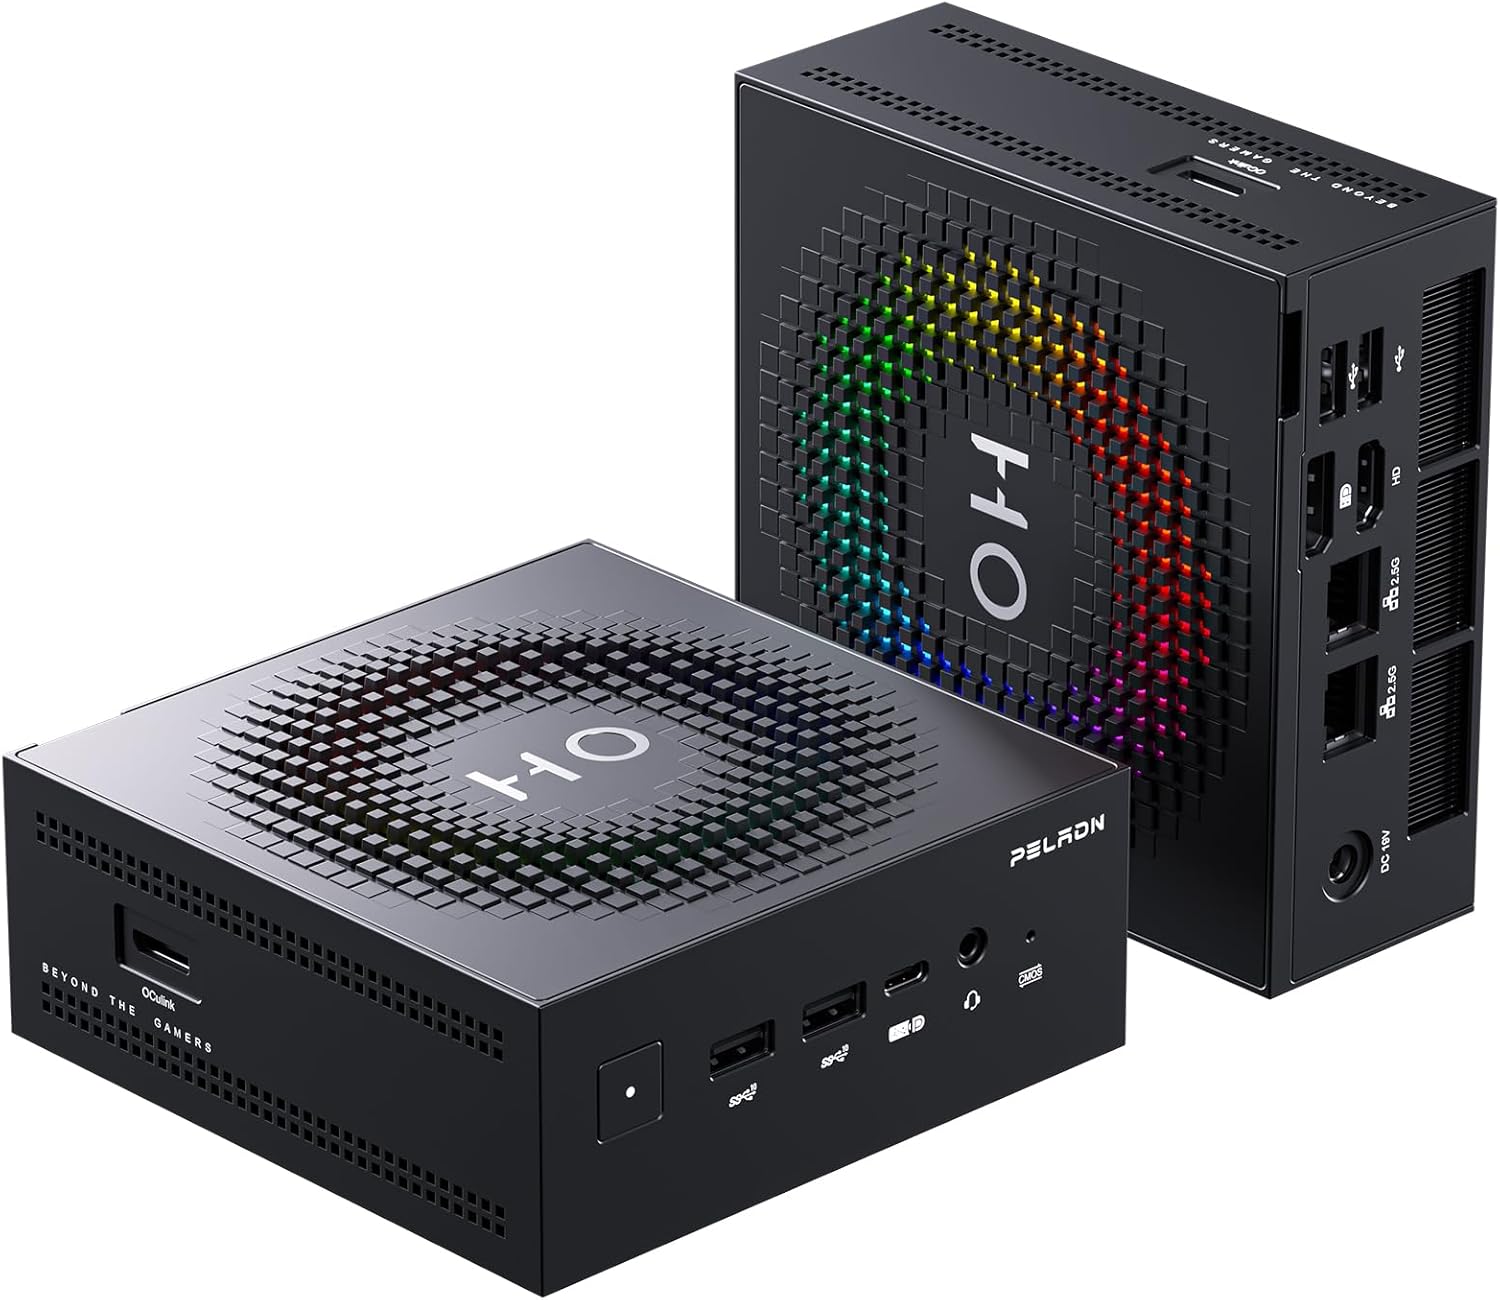
Peladn HO5
A Ryzen AI 9 HX 370 with 32GB of LPDDR5X: enough for 7B–14B assistants and 30B mixture-of-experts models, at a fraction of the price of Strix Halo.
Check current price on AmazonFor an everyday assistant — summaries, writing help, simple coding questions — a Ryzen AI 9 HX 370 is enough. LocalScore measured about 13 tokens per second for Llama 3.1 8B on this chip, which reads fluidly, and about 7 for a 14B model. The HO5 runs the HX 370 at its full 54W and Notebookcheck rated it “good” (81%). Its OCuLink port is the real upgrade path for AI: a desktop graphics card with 16GB of memory runs models that fit in it several times faster than any integrated GPU. Read our Peladn HO5 review.
- Fluid speed with 3B–8B models
- OCuLink to add a desktop GPU later
- Quiet under load, good everyday desktop
- 32GB soldered, no 70B models
- About a quarter of Strix Halo's speed on 8B models
- Dense 14B models are only just fluid
4. Minisforum AI X1 Pro-370 — upgradeable memory
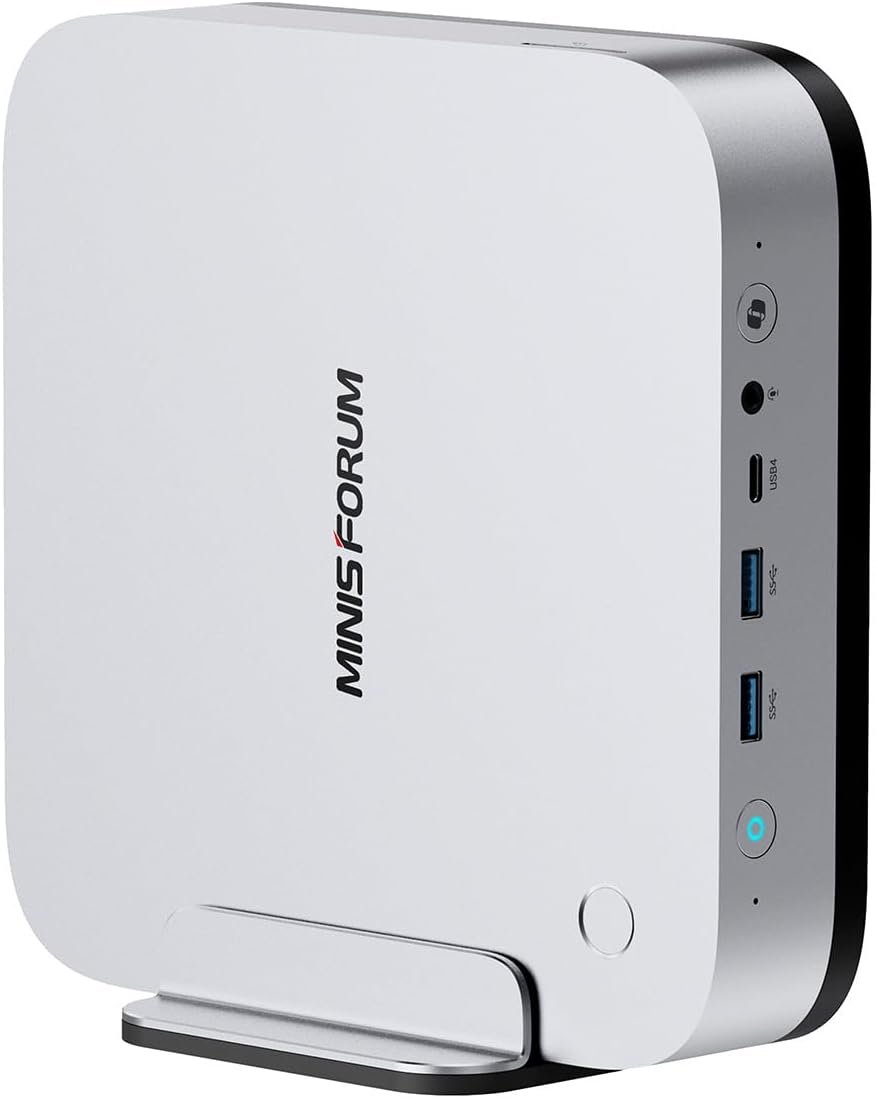
Minisforum AI X1 Pro-370
A Ryzen AI 9 HX 370 with DDR5 in two SO-DIMM slots (up to 128GB), OCuLink, two USB4 ports and dual 2.5GbE.
Check current price on AmazonUpgradeable memory is the AI X1 Pro’s argument: start with the 64GB configuration we link and add more later, which lets large models fit without paying for Strix Halo. The catch is speed. Two DDR5-5600 modules deliver roughly a third of Strix Halo’s bandwidth, so a 70B dense model that fits will run at only a few tokens per second, and the HX 370’s GPU limits prompt processing. It makes sense if model size matters more than speed, or if you plan to add a desktop graphics card through OCuLink.
- Memory upgradeable to 128GB
- OCuLink, two USB4, dual 2.5GbE
- Three M.2 slots, internal power supply
- Slower DDR5 memory than Strix Halo
- Big models fit but answer slowly
- Pricier than other HX 370 boxes
5. Minisforum N5 Max — AI and NAS in one box
A 5-bay NAS built around Strix Halo, with dual 10GbE: the only way to store your files and run AI on them in a single box, for a high price and with immature software.
The N5 Max launched in June 2026 with 64GB of memory, followed by a 128GB version in August. ITPro measured about 72 tokens per second on Llama 3.2 3B and 73 on GPT-OSS 20B using Vulkan, but found Minisforum’s NAS software immature and the default BIOS limiting graphics memory to about 30GB; TrueNAS and OpenMediaVault ran well instead. It suits technical users who want a private assistant searching their own documents. Read our Minisforum N5 Max review.
Also worth a look
- ACEMAGIC Retro X5 — Ryzen AI 9 HX 370 with DDR5 in two SO-DIMM slots, so memory can be upgraded, in a retro console design. Review
- Beelink SER9 Pro (Ryzen AI 9 HX 370) — the same class of performance as the Peladn HO5 from a well-known brand, with 32GB soldered, Wi-Fi 6 and no OCuLink.
- NVIDIA DGX Spark and GB10 mini PCs — 128GB of unified memory with similar bandwidth to Strix Halo, plus CUDA support for AI developers; Linux only and more expensive.
- A desktop graphics card through OCuLink — for models that fit in 16GB, a desktop GPU is several times faster than any mini PC. See what OCuLink is.
Comparison table
The four mini PCs side by side, in the configurations we link.
| Model | CPU | Graphics | Memory | Network | Price |
|---|---|---|---|---|---|
| Minisforum MS-S1 Max | Ryzen AI Max+ 395 · 16 cores | Radeon 8060S (40 CU) | 128GB LPDDR5X-8000 (soldered) | Dual 10GbE · Wi-Fi 7 | Check price |
| GMKtec EVO-X2 | Ryzen AI Max+ 395 · 16 cores | Radeon 8060S · 40 CU (integrated) | 64GB or 128GB LPDDR5X-8000 (soldered) | 2.5GbE · Wi-Fi 7 | Check price |
| Peladn HO5 | Ryzen AI 9 HX 370 · 12 cores | Radeon 890M | 32GB LPDDR5X-7500 (soldered) | 2.5GbE · Wi-Fi 7 | Check price |
| Minisforum AI X1 Pro-370 | Ryzen AI 9 HX 370 · 12 cores | Radeon 890M | 64GB DDR5-5600 · 2 SO-DIMM, up to 128GB | Dual 2.5GbE · Wi-Fi 7 | Check price |
Which software to use
LM Studio for a simple app with a chat window, Ollama for a one-command setup and an API, llama.cpp for the most speed and control. All are free and use the AMD GPU through Vulkan.
- LM Studio: download, pick a model, chat. It detects the Radeon GPU automatically. See our LM Studio guide.
- Ollama: runs a model with one command and serves it to other apps on your network. See our Ollama guide.
- llama.cpp: the engine under most tools; its Vulkan backend gave the best generation speeds on Strix Halo in the September 2026 measurements we cite.
- AMD Lemonade: AMD’s own server, which can also use the NPU for small models; for chat models, the GPU is still faster.
Check the graphics memory setting
On AMD mini PCs, the share of memory reserved for the GPU is set in the BIOS or in AMD’s software (“Variable Graphics Memory”). If a model refuses to load, raise it. Windows caps a 128GB Strix Halo machine at 96GB for the GPU; Linux users report using more.
Local AI or a cloud service?
Local for privacy, offline use and unlimited usage; cloud services for the very best answers and no setup.
The best cloud models remain stronger on difficult reasoning than anything a mini PC can run. Local models are now good enough for summarizing documents, drafting, translation and much everyday coding help, and nothing you type leaves your home. If you handle confidential documents or want to avoid per-use fees, a local machine makes sense; for occasional use, a subscription is cheaper than a 128GB mini PC.
FAQ
What is the best mini PC for local AI in 2026?
For large models, a Strix Halo mini PC with 128GB such as the Minisforum MS-S1 Max or GMKtec EVO-X2: they run GPT-OSS 120B at about 31 to 54 tokens per second in published tests. For 7B–14B assistants, a Ryzen AI 9 HX 370 mini PC such as the Peladn HO5 is enough and costs much less.
Can a mini PC run a 70B model?
Yes, with 64GB or more of memory available to the GPU, but slowly: published measurements on Strix Halo show about 5 to 6 tokens per second for a 4-bit 70B dense model. Mixture-of-experts models such as GPT-OSS 120B are much faster on the same hardware.
How much RAM do I need to run AI models locally?
16GB runs 3–8B models, 32GB runs 14B models and 30B mixture-of-experts models, 64GB runs 32B dense models and tight 70B setups, and 128GB runs 70B–120B models comfortably. On most of these mini PCs the memory is soldered, so choose at purchase.
Does the NPU help with chatbots?
Only a little. The 50 TOPS NPU in Ryzen AI chips powers Windows features and some small models through AMD’s software, but chat models run faster on the integrated GPU. Memory size and bandwidth matter much more than the NPU’s TOPS figure.
Is a mini PC better than a graphics card for local AI?
A desktop graphics card is much faster for models that fit in its memory, typically 16 to 32GB. A Strix Halo mini PC is slower per token but can load models up to about 100GB, which would need several graphics cards. Many mini PCs with OCuLink let you combine both.
Can these mini PCs generate images?
Yes. Stable Diffusion and similar tools run on the Radeon 890M and 8060S through ComfyUI and other apps, more slowly than on an NVIDIA graphics card, with Strix Halo clearly faster than the HX 370.
Related
- AMD Strix Halo explained
- Minisforum MS-S1 Max review
- Minisforum N5 Max review
- Best mini PCs under $1,000
- What an NPU actually does
Sources
- Strix Halo tokens per second, compiled from Level1Techs, llm-tracker.info and ServeTheHome (updated Oct 2026)
- Strix Halo LLM speeds, consolidated measurements (Sept 2026)
- LocalScore, Ryzen AI 9 HX 370 results and local LLMs on a Ryzen AI 9 HX 370 laptop (Apr 2026)
- Notebookcheck, Minisforum MS-S1 Max review
- Notebookcheck, GMKtec EVO-X2 review and 128GB variant (July 2026)
- Notebookcheck, Peladn HO5 review
- ITPro, Minisforum N5 Max review (Aug 2026)
- StarryHope, Minisforum AI X1 Pro specifications; AMD’s Strix Halo vs RTX 4090 claim as reported in January 2025